| country | continent | year | life | population | gdp |
|---|---|---|---|---|---|
| Afghanistan | Asia | 2007 | 43.828 | 31889923 | 974.5803 |
| Albania | Europe | 2007 | 76.423 | 3600523 | 5937.0295 |
| Algeria | Africa | 2007 | 72.301 | 33333216 | 6223.3675 |
| Angola | Africa | 2007 | 42.731 | 12420476 | 4797.2313 |
| Argentina | Americas | 2007 | 75.320 | 40301927 | 12779.3796 |
gog: A Grammar of Graphics
One engine. Every language.
Preface
Be agog. Use gog.

gog is a single graphics engine written in Rust, callable from R, Python, Julia, and JavaScript. Its discipline comes from Hangeul (한글), the Korean alphabet; its vocabulary from Wilkinson’s The Grammar of Graphics (Wilkinson, 2005); and its working shape from ggplot2 (Wickham et al., 2026). Behind all three is one promise: a beginner should be able to read any plot specification aloud on day one and write it themselves on day two.
This preface is unusually long. It explains where the grammar comes from, and why it refuses what it refuses. You do not need any of it to draw a plot. If you would rather start now, take the install command for your language from Installing gog. Then go straight to Part I, A morning, which teaches the whole grammar in a single reading. Nothing in it depends on this page, and you can come back here later.
A grammar, not the grammar
The two titles differ in one small word: Wilkinson’s says The, and this book’s says A. Wilkinson opens his book by defending the definite article in his title. His grammar is a formal system: a fixed set of rules that states what it can build and where it stops. Those stated limits are what make the claim testable. A looser approach, such as a list of chart types, has no such boundary. Nothing says where that list ends, so there is nothing to measure it against. A rival cannot even claim to cover more than such a list, because the list can always grow. Wilkinson wrote down where his grammar stops, and that is why he may call it the grammar.
This book takes the indefinite article on purpose. gog is not a restatement of Wilkinson’s system, and it is not a subset of it either. His grammar rests on an algebra of variable sets, in which * crosses, / nests and + blends. gog’s four operators carry none of those meanings. What gog took from him is the inventory rather than the algebra. Most of the names in its vocabulary come from his chapters on statistics, geometry, coordinates and aesthetics. That is a real debt, and a large one. gog itself is a deliberately small kernel: sources, marks, channels, transforms and operators, with a few more kinds that refine a plot. It grew one decision at a time, and it follows nine laws of its own. The kernel is that whole vocabulary: every name the grammar has, and nothing outside it. The five kinds that build a plot are spelled out later in this preface, and the rest wait for the kernel chapter. When a design question is genuinely open, Wilkinson is still the tiebreaker, and the package carries his book’s name. But the cover says a, not the. gog is one of the grammars that could be built, and it claims nothing more.
The small article also does something the definite one cannot. A Grammar of Graphics abbreviates to agog, English for eager, expectant, impatient to see what comes next. The acronym is not merely lucky; it names the mental state this grammar asks for. A plot is a specification, not drawing code: you never place a stroke yourself. You declare what you want to see, and then there is a gap (brief, but real, and felt every time) before the engine shows you what you said.
Everyone who writes a specification in gog waits in that gap. In this book the waiting is already over, because the engine drew each plot when the page was built. Run one of these code blocks on your own computer, and you do the waiting yourself. An analyst exploring data waits there too, after changing one part of a specification and before the new plot appears. The package is gog; the state of working with it is agog.
gog’s hexagonal sticker shows that state as a picture: a face. Its eyes are + and *. Its nose is / and |, and its mouth is the package name. Those four symbols are every operator gog has.
Each pair has its own place on the face because the two pairs do different jobs. + and * build a single plot, and read as “…and also…” and “…derived by…”. / and | arrange finished plots, and the panels one plot is split into, and read as “…above…” and “…beside…”. One pair composes inside a picture, the other between pictures. The face is the state this section has been describing: someone who has written a specification and is waiting to see it drawn.
Where this began: 1443
gog’s discipline comes from Hangeul, so the story starts with an alphabet rather than with a chart. Nearly every writing system in use today grew slowly, without a plan. Traders borrowed a neighbor’s letters and reused them for the sounds of their own language. Scribes copied picture-signs so often, and so quickly, that the pictures turned into simple strokes. Nobody recorded why any of it happened. Hangeul is the great exception. In the winter of 1443, King Sejong announced twenty-eight letters of deliberate design. The 1446 book that introduced them, the Hunminjeongeum (“The Correct Sounds for the Instruction of the People”), opens by saying why (Sejong the Great and the scholars of the Hall of Worthies, 1446). The spoken language differed from written Chinese, so ordinary people “who have something they wish to say are, in the end, unable to express their feelings.” So Sejong made new letters, few and simple, “wishing only that everyone may learn them with ease and use them daily, with convenience.”

Read plainly, that royal preface is a requirements document. It names the users: not the royal court, but the ordinary people the old system excluded. It names the failure: having something to say and no way to say it. It names the success criterion: easy to learn, used daily. And the book’s postface adds the performance target: a wise man can learn the letters before the morning is over; even a slow one, within ten days. It claims universality, too: with these letters, the sound of the wind, the cry of the crane, the crowing of the cock and the barking of dogs can all be written down.
What made the letters learnable
The design of the letters is what made those claims true. The consonants draw the mouth making the sound. The vowels build from three shapes: ㆍ (araea, a vowel modern Korean no longer writes), a dot for heaven; ㅡ (eu), a flat stroke for earth; and ㅣ (i), an upright stroke for the human standing between them. Linguists eventually had to coin a new category, featural, for a script this systematic (Sampson, 1985). In a featural script the shape of a letter shows a property of the sound it makes.
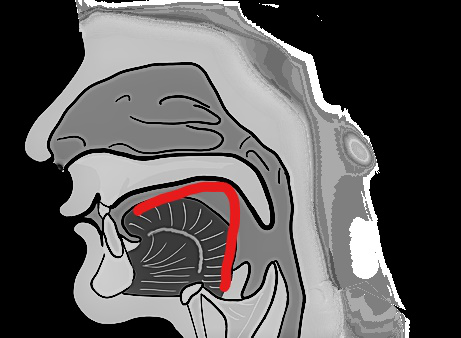
Twenty-four of Sejong’s twenty-eight letters are still in use today. That small number is the usual explanation for how quickly Hangeul is learned. English has a small alphabet too, and still takes years to learn, because its spelling is full of exceptions. The same four letters, ough, are pronounced six different ways, and none of the six is a rare word:
| word | ough is pronounced |
|---|---|
| though | like o in go |
| through | like oo in too |
| thought | like aw in law |
| tough | like uff in stuff |
| cough | like off |
| bough | like ow in cow |
Hangeul is learnable in a morning because its composition has no exceptions. An atom is a piece that nothing divides further, here a single letter. The power is not the atoms. It is the regularity with which they combine.
Not everyone at the royal court wanted the new letters, and the people who opposed them understood exactly what would be lost. In 1444 a senior scholar of the court academy petitioned against the new script. Civilized writing meant Chinese characters. The clerks already had a workaround, 이두 (idu), and it served everyone who had trained in it. And if letters were easy, people would abandon the hard study through which learning had always been earned. It is the eternal argument of the fluent expert: the difficulty earns its keep; my fluency is capital. You have heard its modern form: everyone already knows what alpha means. In plotting libraries alpha means opacity, and the argument assumes everyone has already spent the time to learn that. Sejong overruled it. The script outlived a royal ban in 1504 and survived five centuries in private letters and popular novels. It was named Hangeul around 1912, and it is today the alphabet of one of the most literate countries on earth. Systems that are well defined and easy to use survive, because every new learner is one more person choosing them.
The same problem, in graphics
Now look at the tools used to draw data. Most work like logographies, writing systems in which each symbol stands for a whole word. They are lists of chart types, each memorized as a whole. A histogram function here, a pie function there, each with its own arguments in its own order. That is the logographic problem of graphics: not a grammar but a list of special cases, usable only after long training.
That problem already had its reformers. Wilkinson found the grammar that those chart types share, and ggplot2 carried it into the daily work of hundreds of thousands of people (Wickham, 2008, 2016). The two of them did for graphics what Sejong did for writing. They traded a list of memorized charts for a real, generative language, and a better one than anything built before it. gog is built on that achievement and in its debt. It adds a single ambition of its own, the one Hangeul is famous for: no exceptions in how the pieces compose. That is the standard gog sets for itself, and the aim is that any plot you can picture is easy to describe in a sentence.
That debt is made of specific things, and naming them is better than a vague mention. The + that joins the parts of a sentence is ggplot2’s, not Wilkinson’s, whose + blends variables and is a different operation entirely. The split between mapping a column and setting a fixed value is ggplot2’s. So is drawing several marks over one pair of axes. So is the idea that a plot is a specification you build and hand over, rather than a set of drawing commands. Wickham named that last one himself. “One of the most important features of the grammar is its declarative nature,” he wrote, and ggplot2 uses + to keep it that way in R (Wickham, 2008). This package inherits both the property and the operator that protects it. Wickham has since said publicly that the pipe (R’s |>, which chains one call into the next) would have been the better interface. In the same answer he says ggplot2 cannot switch to it, and that a new package just to make the change would not be worth it (Wickham, 2018). gog keeps +, and the operators chapter says why. A reader who already writes ggplot2 will recognize the shape of almost every sentence in this book. That is on purpose. After years of ggplot2, its grammar is how I think about visualization, so it is the shape this one took.
What changed is narrower, and it is why this package exists at all. ggplot2 already derives a histogram, from its bar geom (the shape it draws, which gog calls a mark) and its binning statistic (the counting step, which gog calls a transform) (Wickham, 2016). What it adds is a shortcut name for that pair, geom_histogram(). gog adds no such name, so writing the pair, bar * bin, is the only way to draw a histogram. One engine answers four languages, so the sentence you learn in R is the sentence you write in Python. And the rules for combining the pieces hold everywhere, with no exceptions, which is what the rest of this preface is about.
So gog invents no new charts, the way Hangeul invented no new sounds. It repeats Sejong’s question, asked in full: not which charts should exist, but what is the smallest set of letters, and the most regular rule of composition, from which every chart can be derived? Wilkinson’s grammar answers what can be drawn (Wilkinson, 2005). ggplot2 found the shape that made that answer usable, and most of how a sentence here is assembled is ggplot2’s idea. Hangeul disciplines how the pieces compose. Marks are the consonants, silent until placed. Positions (channels such as x and y) are the vowels that give them somewhere to stand. A mark and its positions together are a syllable, and nothing smaller draws. A histogram is nothing to memorize: it is bar * bin, a bar mark derived by binning, the way ㅋ (k) is derived from ㄱ (g) rather than invented fresh.
Here is a histogram of life expectancy, drawn from the table gapminder_2007. The table holds 142 countries in 2007, each with its life expectancy (life) and its GDP per person. Its first rows are shown below.
data(gapminder_2007) + bar * bin + x(life)data(gapminder_2007) + bar * bin + x(col.life)data(gapminder_2007) + bar * bin + x(:life)plot(data(gapminder_2007), layer(bar, bin), x(col.life))“Given gapminder 2007: bars derived by bin, x is life.” The code above is the whole specification, and the engine drew the plot from it when this page was built. There is no histogram function in this package and no argument that turns bars into one. data(gapminder_2007) is the source: it names the table (142 countries, one year) that supplies the rows and the columns. bar is the mark, the shape drawn for each row, the way ㄱ shows the shape of the mouth that says it. bin is the transform, which derives new values from the columns you named: here it cuts a continuous column into intervals and counts the rows falling into each. x is the channel, the visual property a column is mapped to. Here it is a position, the vowel of this sentence: it gives the bars somewhere to stand. And * is the operator that puts a transform on a mark. It is the derived by in the sentence above. Do not read * as a multiplication sign, because nothing is multiplied.
The table gathers the five parts of the sentence in one place.
| Part | In the sentence | What it does |
|---|---|---|
| source | data(gapminder_2007) |
names the table the rows come from |
| mark | bar |
sets the shape drawn |
| transform | bin |
cuts life into intervals and counts the rows in each |
| channel | x(life) |
sets the horizontal position from life |
| operator | * |
puts the transform on the mark |
Nothing there is memorized. The names are ordinary English words, and the rule that joins them never changes. Knowing those five parts is knowing this plot. Every other statistical chart in this book uses some of these same kinds of part, and many need no transform at all.
And one law applies to the whole package: no exceptions. A rule you learn on one mark holds on every mark, or the package has failed you.
What the grammar refuses
The no exceptions law is easy to read as everything combines with everything. Here is the other half of it, and it is the half that matters more.
Hangeul can write the crowing of a cock. Hangeul cannot write ㄱㄴ (g then n). A syllable is not a pile of letters. It is a set of three slots: an initial consonant, then a vowel, then an optional final consonant. Consonants fill the first and last slots, and a vowel fills the middle one. Two consonants with no vowel between them do not make a syllable, because the middle slot is empty. ㄱ on its own is silent, and ㅏ (a) cannot stand alone either. To write that bare sound you supply ㅇ, a silent carrier letter, for the empty initial slot, and what you write is 아 (a). The same script that can write the barking of a dog refuses most combinations of its own letters.
Those are not two facts. They are one. If the slots were removed, and any letters could stack in any order, the script would not become more expressive. It would become unreadable. A written syllable would no longer tell you how to say it, and you would return to memorizing whole shapes, which is how writing began. The refusals are what make the script readable at first sight. A reader meeting a syllable for the first time still knows which part is the consonant, because nothing else could have been in that slot.
A plot is the same. gog will not draw a point from an x alone. A mark with one position has not said where to put it. gog will not map a column to shape on a bar either. A bar is a rectangle, and there is no other shape for it to be. Neither refusal is a missing feature. Both exist for the same reason: they let you read a specification you have never seen before. If every mark accepted every channel, knowing the mark would tell you nothing. A plot would again be something you memorize. The engine says no out loud, and every no points to what you meant instead. That is why this book renders its refusals live, on the page, beside the plots that work.
These refusals keep the set of atoms small, and a small set is the goal: one that draws every plot, the way one small set of letters writes every Korean sound. Neither set claims to be complete.
Hangeul does not write everything. It does not mark tone, and it does not mark how fast a syllable is said. Some sounds it cannot spell at all. Those gaps were left as gaps, because the sounds behind them are not the ones most speakers need. The letters were not built to be perfect. They were built to be a means of writing sound.
gog is built the same way. It does not promise that every visualization is possible. Reaching some of them would mean stepping outside the grammar’s own rules and adding an exception, and no chart is worth that.
What the grammar will not do is refuse a plot for being a bad idea. 꿲 (kkwek) breaks no rule of Korean, and no one has ever needed to write it. Its graphics equivalent is a color scale (the rule that turns a column’s values into colors) stretched over three hundred categories. That plot is legal here, because well-formedness and usefulness are different judgments, made by different judges. The engine guarantees well-formedness, always. Deciding whether a plot is useful is your job, and most of this book is about that.
The promise, and the book’s rules
This book inherits the 1446 promise, restated for graphics: read the whole grammar in a morning; write it fluently within ten days. Part I is built to be finished in a single reading. The rest of the book deepens what the morning introduced; it never replaces it.
Six rules govern every page, and you can hold the book to them:
- Every plot is live. Each is drawn by the engine as the page builds; no plot in this book is a screenshot. The only static images in this book are in this preface (the Hunminjeongeum page, the mouth saying ㄱ, the diagram of how a plot is drawn, and in the web edition the cover and the DOI badge) and none of them is a plot.
- Questions first. Every teaching chapter opens with a question, never with a feature name. The teaching chapters are those in Parts I to IV.
- An ending, not a stop. Every teaching chapter outside the cookbook closes by saying what its subject cannot do, and which chapter answers that. It is not a summary of what you have read.
- A small cast. Nine families of table carry more than two out of three plots in this book. A chapter that needs a table of its own introduces it where it is drawn. New columns cost the reader attention, so the variety stays in the questions.
- Read it aloud. The first specification in every teaching chapter is followed by its English sentence. Read that one aloud, and the rest of the chapter reads the same way. If a sentence cannot be read aloud cleanly, that is a bug in the grammar, not in you.
- Errors on stage. Refusals render live in these pages, because the engine’s no, always with a direction, is half of what it teaches.
One thing to be clear about before you start: this package is young. The version number is 0.6.2. A leading zero means the package has not reached its first stable release. The grammar is settled enough to build on, and the implementation is not finished. What exists is a first working version, so do not expect everything to work the first time. If you use it for an experiment or a paper, you are taking a risk. This warning is here so that the risk is one you chose, and not one you found out about later.
Expect it to move quickly. New features will arrive often. New atoms will not: the kernel is meant to stay small, and it grows one decision at a time. A plot you describe today may have a shorter sentence next month. What I will try hard not to do is take anything away. A sentence that draws today should still draw a year from now. If that ever has to break, I will say why rather than let it break quietly. I cannot promise it, though, and before version 1.0 nobody honestly could.
This book moves with the package. Because every plot here is live, a change to the engine reaches these pages the next time they are built. The text is rewritten whenever it stops matching. Expect the book to change as often as the package does. What each release changed is recorded in the package’s changelog.
A book that changes this often has one consequence, and it matters when a sentence refuses on your computer. These pages are built from the newest source, and a released package is not. So the book can describe something your copy does not have yet. All four packages change only when a new version is published. If a sentence here refuses for you, and the message does not recognize a word this page uses, check your version before you doubt the page.
Please report the bugs you find. A package this young improves mainly by being used, and that is what I am hoping for. When a plot is drawn wrong, save it with save_json() and attach the file to your report. The engine can draw your plot again from that file alone.
One kind of report is worth more than the others, and it is the one I cannot write myself. Take a dataset you know well and draw it in gog. Then draw the same thing in a tool you already trust. Any tool at all: ggplot2, matplotlib or seaborn, Excel or Tableau, Stata or SPSS, Vega-Lite, Plotly, Bokeh or D3. Put the two pictures side by side and tell me where they differ. A standard dataset is ideal, because the picture it should produce is already familiar to everybody.
Here is why that comparison is worth so much. This package tests itself thoroughly, but in one direction only. Every sentence in this book is drawn in all four languages, and the four files have to match byte for byte. Every refusal on these pages is run again on every build. All of that proves gog agrees with itself. None of it proves the picture is right. A box whose whiskers reached the wrong value would pass every test this project has, four times over, in four languages. This book would print it on the page as though it were correct.
A difference is not automatically a defect, and it is fair to know that before you spend the time. Some differences are decisions. A gog box spans the quartiles, as most software does. Tukey’s original spans the hinges, the median of each half of the data. The two agree whenever a group holds an odd number of values. The box chapter says so and says why. So a comparison gets one of two answers: this is a bug and thank you, or this is a choice and here is the reasoning behind it. Both are worth the message.
Not everything reported will be built. I am this project’s benevolent dictator for life. The title is a joke, and each word in it means something. Dictator, because the founder decides instead of the project voting. For life, because there is no election to lose. Benevolent, because the decisions are expected to serve the users rather than the founder. It was first used in 1995 for Guido van Rossum, who created Python. Many people would say I am not qualified to hold it. I am holding it until this package is in the hands of a user community and of people better than me.
The cast
The fourth rule promised a small cast: nine families of table. Meet them once, here:
gapminder_2007: 142 countries in 2007, withgdp(per person),life(expectancy in years),population,continentandcountry. The table this book uses most, and an excerpt of the Gapminder Foundation’s data (Bryan, 2025).gapminder_asiais five Asian countries traced 1952–2007, andgm_allis every country and every year.iris_flowers: 150 flowers, withsepal_length,sepal_width,petal_length(all in cm) andspecies. Three measurements on one scale, and a category that separates cleanly. The measurements are Edgar Anderson’s, and they reach most software through Fisher’s 1936 paper (Fisher, 1936) and R’s owndatasetspackage (R Core Team, 2026).medals: five countries’ Olympicgold,silver,bronzecounts. Small enough to check by eye.actualsandforecast: yearlysales, history in one table and expectation in another. The two-table pair.six_weeks: 42 consecutive days oforders, withdaystored as a realDate, for calendar axes.winds: 264 wind observations, withdirection(eight compass points),bearing(in degrees),speedandseason. The wind rose in polar reads it, and so do the book’s reference-line and band examples.titanic: the passengers and crew of the Titanic as 32 groups, withclass,sex,age,survived, andn(the number of people in each group). R’s own classic table (R Core Team, 2026), reshaped to long form, and the book’s table of movement. Every flow diagram with stages reads it.trade_partners: 22 trade relations between 15 economies, withexporter,importer, andbillions(the value of the goods traded, in billions of dollars, rounded). The book’s one table of relations. Every network diagram reads it, and so do the arc diagram and the chord diagram.commutesandspending: the book’s two tables of parts, where every number is one piece of a whole.commutescounts how 3,790 people in four cities travel to work, withcity,modeandpeople.spendingis one month of a household’s spending, withgroup,item,detailandamount. Its first three columns are levels: each item belongs to a group, and each detail to an item. The sunbursts in the polar chapter readspending, and the mosaic in the transforms chapter readscommutes. Parts of a whole reads both.
Those nine families answer most of the questions asked here. A few questions need a shape none of them has, and each of those tables is introduced on the page that first draws it rather than in this list. The surface chapter uses a mountain’s elevation grid, and the space chapter follows two gliders’ spiral flight paths through the third dimension. The map chapter draws country boundaries, and the globe chapter draws earthquakes under the Pacific. The cluster transform reads foods and their nutrients. The rule chapter reads thresholds, and the zone chapter reads the spans it shades. Some of them return in later chapters when the same shape is needed again, and each is shown again where it returns. None of them arrives to add variety. A new column costs the reader attention, so the variety in this book stays in the questions.
How this book runs
The shape of the book borrows from the Hunminjeongeum itself. That book stated its whole system in a few pages, then explained each letter class, then showed assembly, then ended with ninety-four ordinary words in use:
- A morning: the whole grammar, fast. This part has a first plot, the kernel in one table, reading practice, and writing practice.
- The letters: each atom family in depth. This part explains the data you bind once, the marks, the scales, the refining channels, setting vs mapping, and the transforms.
- Sentences: composition. This part explains layering, deriving, scope, faceting, and arrangements of whole plots. Then it has one chapter each on movement from place to place, similarity drawn as a tree, the third dimension, polar coordinates, packed regions, the flat map, the globe, networks, a plot played in time, and the reader’s own selections.
- The cookbook: recipes organized by your columns and your question, never by chart name. Many of them also show the sentence one atom away.
- The reasons: the nine laws the package never breaks, and why.
- The host language: one short chapter apiece for R, Python, Julia and JavaScript. A binding is the package that lets one language write
gogsentences and send them to the engine. These chapters hold what belongs to the host language rather than to the grammar.
Six appendices follow. The kernel card is the whole vocabulary on one page. Functions around the grammar documents the few helpers that are outside it, gog_table() among them. The combination grids cross marks with channels, with transforms and with spaces, and transforms with each other. Each shows what combines and what the engine refuses, generated from the engine’s own rule table on every build so it cannot drift from the code. A dictionary runs from chart names to sentences. A phrasebook translates ggplot2 into gog. And coverage closes the book, listing what gog and ggplot2 each draw that the other does not.
This book is written in R. Python, Julia and JavaScript speak the same sentences into the same engine. The four binding chapters, R included, are the whole of the difference. They cover how each language captures a column name, and, for JavaScript alone, the four words it needs because it cannot give + * | / a meaning of its own. Most code blocks are executed as the page builds: the plots you see are drawn by the engine at that moment.
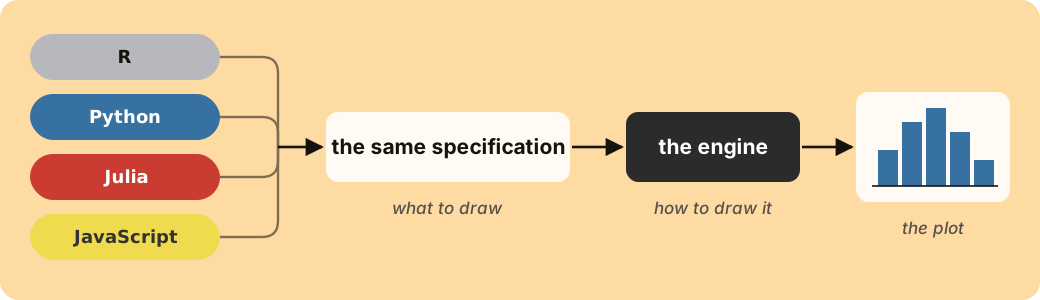
A code block that is a gog sentence also carries a tab per language, so you can read the same sentence in whichever one you write. A few refusals appear in R alone. They are mistakes a language’s package catches before the engine sees the sentence. All four packages refuse them with the same message, but the code in the message follows each language’s spelling (gdp in R, col.gdp in Python), so the book shows the R one.
Some code, such as x(life, limits = c(37.5, 87.5)), is written inside the text rather than in a code block. That code has no tabs, so it is written in R. In the other three languages, a column is written in that language’s own way, and so are values such as c(37.5, 87.5) and TRUE. The chapter for each of those languages has a table that spells these values: Python, Julia and JavaScript.
Installing gog
You have seen the plot the engine drew on this page. All four bindings work. Copy the command for your language, and read the notes that follow.
R
install.packages("gog", repos = c("https://psychometrician.r-universe.dev",
                                  "https://cloud.r-project.org"))
Python
pip install gogJulia
using Pkg; Pkg.add("GrammarOfGraphics")JavaScript
npm install grammar-of-graphicsThe package has two names, and the registries are the reason rather than the grammar. In R and in Python it is gog, because a three-letter name is allowed in both. Julia requires a package name of at least five letters, in capitalized words, and npm already had a package called gog. So those two spell the name out instead, each in its own style: GrammarOfGraphics in Julia, and grammar-of-graphics on npm, which does not allow capital letters.
The Python package carries the engine inside it, already built for your computer; the Julia and JavaScript packages download it when you install them; and the R package carries it on macOS and Windows. So, except for R on Linux, you do not need a Rust (Klabnik & Nichols, 2023) toolchain, and nothing has to be added to your PATH. On Linux the R command builds the engine from source. Before you run it there, you need Rust 1.75 or newer and a network connection. The R chapter gives the command that installs Rust. The other three commands can be run as they are.
The R package is not on CRAN yet. It is published on r-universe instead, which is why the repos argument names two addresses. The second address is an ordinary CRAN mirror, and it is there so your other packages still install as usual.
Each binding has its own chapter at the end of this book, and each of those chapters carries the longer version of this section: R, Python, Julia and JavaScript.
Every one of these packages is at version 0.6.2. The grammar is settled and the engine draws this whole book, but the packaging is new, so releases will be frequent, and most of them will not change the vocabulary. One promise holds at every version: every page shows what the engine actually did. If a page shows a sentence, the engine drew it. If a page shows a refusal, the engine refused it.
The prose in this book is licensed CC BY-NC-SA 4.0. The code is licensed Apache 2.0, the same license as the engine, so the examples can be used in your own work.
This book is archived on Zenodo and can be cited by its DOI, 10.5281/zenodo.21807652. That address always resolves to the newest deposited edition. The archived copy stays available even if this site does not.
Translations
This book is being translated, starting with Korean, then Spanish and Simplified Chinese. A translation keeps the code, the data, the plots, the engine’s messages and the grammar’s vocabulary in English. It translates the explanation around them, so the code you learn in one edition runs unchanged in every other.
You can help in two ways. If an edition exists in your language, read it and tell me where a sentence reads like a translation instead of like your language, or where a word is not the one your readers use. If your language has no edition yet, Dutch for example, and you would like one, say so. Any language whose readers want an edition can have one, and you are welcome to start it; I will help you set it up. Either way, write to me on GitHub and name the language.
Who wrote this
The cover names one person and the Claude models that worked with me. The division of labor behind those names is worth stating plainly rather than leaving in a footnote.
The first name on the cover is not a name. I publish as psychometrician. I learned what a pen name was in 1992, when I took introductory statistics in the psychology department. That is where I met Student. Student was William Sealy Gosset, an English chemist and statistician, and the t-distribution carries his pen name instead of his own. My own papers are few, and no academic journal would let me publish under a pen name. This book is the first chance to use one.
The word does a second job. Most people do not know the job title, and anyone who uses this package now knows that a psychometrician started it and maintains it. What they are less likely to know is how much psychometricians care about data visualization. As far as I know, only one academic journal runs a visualization competition, and it is ours: Educational Measurement: Issues and Practice, published by Wiley for the National Council on Measurement in Education (NCME). Every year it asks its members for thoughtful and creative diagrams that communicate a clear message about educational or psychological data. The winning entries become the journal’s covers, and the next best entries are shown inside. The cover gallery is worth your time. This package may not be able to draw all of them.
Psychometricians have cared about data visualization for a long time. My own history with it starts in 2005. I was writing my dissertation, and every conditional plot in its simulation chapters was drawn by the lattice package (Sarkar, 2008). It was the first graphics tool that impressed me. After that I was a heavy ggplot2 user for years. What changed was the day I understood that ggplot2 had a grammar. From then on it felt like there was no end to the plots I could make.
I owe Hadley Wickham more than a citation for that. Before his package and his book, a plot was a task to get through. You looked up the function for the chart you had been asked for, learned whatever arguments it happened to want, and moved on. The grammar changed what the work was. Visualization became a creative act rather than an item on a list. It is creativity inside a boundary, the one the grammar draws. That is the part I most want to pass on.
That is the story behind the first name on the cover. Here is how the work was divided between that name and the models. The main rules are mine: the founding question, the Hangeul discipline and the nine laws. Many of the more specific rules came out of working with the models, and the ruling at every fork about what this grammar would and would not become is the part I am answerable for. The hex sticker is mine as well. I designed it myself in Canva, with no sticker package. I am not an artist, and what I wanted was not a beautiful sticker but an unmistakable one. The Rust engine was written entirely by the Claude models on the cover, as were all four language bindings and the test suites. They also did the work nobody is ever thanked for, which is running every sentence in this book through four languages, again and again, until all four agreed byte for byte.
The text is a third case, and the closest comparison is a ghostwritten autobiography. The public figure named on its cover usually did not write the words. A professional writer interviews the subject and writes the book, so the thinking is the subject’s and the prose is the writer’s. These pages began the same way. I decided what kinds of chapters the book needed and what kinds of examples each one should show. The models wrote the first drafts under my supervision. One thing differed from a ghostwritten book: not every idea in this book came from me. The models often suggested something better than my first idea, and my task was to accept it or reject it.
For each chapter, the first draft was the start of the work, not the end. I read every chapter and every section of this book. I read them in three roles: as an editor, as a reviewer, and as a reader giving feedback. The models then revised each section, following my editing guidance and feedback. That guidance changed every section in this book, and none was left as it was first drafted. The models wrote the sentences; the decisions behind all of them are mine.
Naming the models as co-authors is meant literally. A line reading “with assistance from” would describe far less work than the models did. They were not one kind of collaborator, and it would be a poor tribute to pretend they were. On some days they were assistants: fast, tireless, and so eager to be useful that “done” tended to arrive some time before done did. A change to how bars are drawn was once confirmed by checking a stroke color instead of looking at the plot. The report said all was well while every bar on the page was still wrong. Most of the checks now guarding this repository exist because of an afternoon like that, and not one of them was added to catch a careless human.
On other days they were advisors, and that is the part I did not expect to be writing about here. A design question asked at the wrong hour, asked badly, asked for the third time in a worse form than the first: it got taken as seriously as if it were a good one. When I asked “why not just…?”, the answer was a patient account of what the shortcut would break, not an agreeable yes. A fair number of the refusals in this engine came out of working through questions like that together. Some of the reasoning in Part V became clearer in arguments where the model pushed back on me. An assistant that agrees with you is the easy thing to build. This grammar would be a good deal worse if that is what I had had.
Taken together, it felt like a research meeting. Smart researchers filled the room, eager to listen to me and eager to carry out the plan once I had decided. I have not had both of those at once before. It was always a good time, and sometimes an expensive one. A small question would open into a long detour, and I would lose several hours in it. Accepting that invitation was my decision every time, so none of this is a complaint.
Responsibility does not divide the same way. Every error in these pages, every refusal the engine gets wrong, and every design decision that turns out to have been the wrong one is mine, because I chose it and I kept it. I organized this project and I maintain it. The credit is shared; the fault is not.
One last item belongs in an honest accounting. I work as a psychometrician, and this package was never part of that job. It was built late at night, on weekends, and on vacation days. That time belonged to my wife and daughter, and I spent it talking to the Claude models on the cover instead. I am not going to call that devotion to the craft. To my wife and daughter: sorry. I would like to end by saying it is finished. It is not. The version is 0.6.2, and what comes next will cost the same nights, weekends and vacation days.
Thanks to Posit
Two acknowledgments close this preface. The first is to a company whose tools this book is built on.
Posit PBC, called RStudio PBC until 2022, builds a large part of what a working R user touches in a day. The parts I depend on are free, and there are three of them.
The tidyverse (Wickham et al., 2019) is the one I would miss first. It is the vocabulary I think in when I handle data, and has been since long before this project. You will not find it in this book, whose tables are built in base R. I want gog to install anywhere, so it needs only one package beyond R itself, jsonlite (Ooms, 2014). That is a rule for the package. It is not how I work the rest of the day.
Their editors are the second. I worked in RStudio for years, and I work now in Positron, which is newer and holds R and Python in one window. The two are not the same program under different names: RStudio is still here and still maintained, and Positron is a second program beside it.
Quarto is the third, and it belongs here rather than in a colophon, because the first of the six rules above rests entirely on it. Every plot is live is a claim about honesty rather than convenience. Every code block on these pages ran while the page was being built. One that draws a plot really drew it, and one that shows a refusal was really refused. Quarto is what executes those blocks. Without it, every plot here would be a screenshot and every code block would be text that nobody had run. The book would slowly stop matching the package it describes, and no one would notice.
Quarto gives the book three more things it could not have faked. Four languages spell the same sentence in one tabbed block, so a reader sees the parity instead of taking it on trust. One source builds both an HTML site and a printable PDF, Korean letters and all, from the same executed chunks. And a block is allowed to fail without stopping the build, so the engine’s refusals appear beside the plots that work instead of in an appendix.
None of that announces itself while you read, which is the mark of a tool doing its job well. Without Quarto there would be no book here at all.
I will not be modest about what the tidyverse and their editors are worth either. My work as a psychometrician would be harder, and a good deal more miserable, without what this company gives away. Thank you.
Thanks to Anthropic
Soon after Claude was released, I built a web application. It was React on the front, Supabase for the database, and the Google APIs behind it. I did not know React well, and I did not know Supabase at all. The application got finished anyway.
Then it failed, and the reason had nothing to do with the code. I could not market it. I did not know how to reach the people it was built for, and after a while I shut it down. The application is gone. Its tutorial videos are still online: eighty of them, in most major languages. Two are the English ones, if you would like to see what it did: tutorial one and tutorial two. Claude Code did the translating for the rest.
The lesson was not the one I went looking for. Building the thing was no longer the hard part. If I plan carefully, keep going, and work through the problem with Claude Code, I can finish what I set out to build. So I began to want something else: my own packages, in the two languages I actually work in, R mainly and Python occasionally. This package came from that wish.
The application left me a skill as well: designing an interface. A web application is mostly interface, so I had to learn to design one. I drew every screen on paper before it was built. I did the user-experience work myself, and tested it over and over. This package asks for almost none of that skill. A plot is not an interface, and the engine has no screens. The exception is selection. Claude Code wrote the code for the controls under a brushed plot, but their design is mine: their names, what a single click does, and which pointer means which mode. It is a very small piece of design next to that application. I hope you like it anyway.
A grammar of graphics is a larger promise than a web application. It is an engine, and an engine has to be written, tested, and kept working. I am a psychometrician, with no team on this project, no funding, and no ability to write Rust. Without Claude Code, this package would still be a plan.
One more item belongs on that list. English is not my first language. Every conversation behind this package was held in my own broken English, from the first design question to the last bug report. I chose the wrong words and put them in the wrong order. I left out the small words that hold an English sentence together. Claude Code understood what I meant nearly every time. Twenty years of thinking about this field reached the engine through sentences full of mistakes. None of that thinking was lost on the way. You can do better than I did.
I think this may have been luck, and I would rather say so than not. I happened to be thinking about data visualization. I happened to be thinking about Hangeul. Then Claude Code arrived. What I did was stand between the two and let them meet.
There is nothing rare about that position. Anyone could be standing in it. If you have been thinking about your own subject for a long time, and you are willing to play with this tool, you are already there. Much bigger things than this package will come out of that.
So, thank you to the people at Anthropic who built Claude Code, and to the models named on this book’s cover. I do not know most of your names. I know two of them from YouTube: Boris Cherny and Cat Wu. You built the thing that let a psychometrician write a graphics engine in Rust. How cool is that? Thank you.
Image from Wikimedia Commons; public domain. The copy shown here adds a white ground and a margin, so that the letters read the same in either theme.↩︎
Diagram by Paranocean on Wikimedia Commons, used unchanged under CC BY-SA 4.0. It keeps that license rather than this book’s.↩︎

